

How The Tech Clouds Built a Smarter Website & Server Monitoring Solution
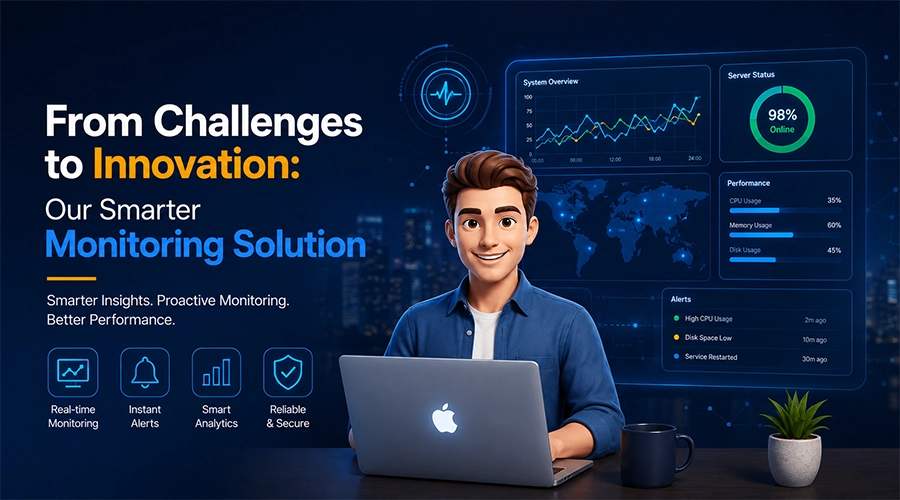
Your website looks nice; nothing felt off. The server seems to be up; who knows? But then you wake up at 2 AM to check whether everything runs as you wish. After a hectic schedule, it’s tough to monitor everything; is there a solution? Yes, of course.
Knowing your concerns, The Tech Clouds (TTC) developed a website and server monitoring tool that keeps an eye on everything you need to monitor throughout the day. It can tell you whether your API is slow or your certificate is going to expire or not.
It signals an unhealthy server and offers alerts if something feels out of place. But what’s the name of the website monitoring tool they made, and why are so hype about it? The name is AlertSpy, and what’s the big deal about it?- Well, you will get to
know about that soon!
Key Takeaways
- The Tech Clouds TTC builds website and server monitoring tools that can catch problems even before customers do.
- It constantly monitors server health, including Docker, Network, Prometheus, Kubernetes, Cloud, and many more.
- AlertSpy, TTC’s uptime monitoring solution, helps DevOps Teams, cloud experts, SaaS companies, and IT Ops teams.
- It covers domain failure, SSL certificate expiration, predictive monitoring, anomaly detection, reporting, incident tracking, and more.
- We use the best technologies to build this tool and follow up a detailed monitoring pathway that looks something like this: Monitor → Detect → Analyze → Alert → Route → Respond → Learn workflow.
What Is a Website & Server Monitoring Solution?
Okay, before understanding AlertSpy, learn what a website and server monitoring solution is; only then can you see the value AlertSpy adds to your system. A website and server monitoring solution continuously checks whether digital services are available,
responsive, work at the desired pace, and functioning as expected. It’s just a set of eyes that never blinks. Humans get tired, which is obvious, but they don’t keep websites and servers at their optimum level almost all the time. Oh sorry! Not just servers,
databases, URLs, response times, applications, SSL certificates, domains, APIs, ports, and other infrastructure signals. It can catch a slow, simple leak before it causes major havoc, paired with a solid website uptime monitoring service. To be honest,
we’ve always wanted to build a tool that can flag trouble before a single customer even notices, and we live up to our promises through AlertSpy. Just tell us what you want. Is it ping monitoring? Domain or port monitoring? No? Then maybe Kubernetes monitoring
or Cron job monitoring? If not, maybe you want network monitoring, cloud monitoring, or just to prevent website downtime. For all your monitoring,
AlertSpy does it all, automatically. Keeping it for your business means handing over your headaches to someone else.
An Innovation for Website & Server Monitoring Domain Built by The Tech Clouds (TTC)
AlertSpy grew from a problem TTC experienced internally: teams often had to look across different systems to understand whether a website or infrastructure component was healthy. What if your website is slow– who’s gonna tell you about that? What if your server cannot detect flaws quickly and breaches happen in a flash? What on Earth will be there to take that responsibility if any customer details
are lost or you lose your own business information? Honestly speaking, we have gone through many such doldrums, and then thought of building something monitoring tools that
can keep you alert every second. AlertSpy is the result of that hard work, so other businesses never have to be in hot water like we were many times. It brings constant checks into a centralized SaaS platform for IT Operations, DevOps engineers, system
administrators, and growing SaaS businesses. The platform combines website uptime monitoring, infrastructure checks, incident notifications, response-time visibility, and status communication in one environment. AlertSpy’s current platform also supports
integrations with Slack, Microsoft Teams, Google Chat, Discord, and email.
What Problem Does AlertSpy Solve?
Now, come to the most asked question: what problems does it solve? The answer is simple: ask us what it cannot solve. Well, before you get more perplexed, let us help you understand what it does:
1. Uptime And Downtime Detection
A failed URL is just the start of an accident, but unlike other monitoring tools that generate signals only after an incident is complete or after receiving complaints, AlertSpy keeps you aware of it beforehand. So, teams can identify website downtime
before customers start reporting it. This approach also makes a website uptime monitoring service more useful because teams can act on problems instead of discovering them manually.
2. Server Health And Resource Monitoring
A website can be online while the server supporting it is struggling. What will notify you about CPU spikes, memory leaks, disk space filling up, I/O bottlenecks, and unexpected traffic surges? Without AlertSpy, it’s difficult to get notifications about
all these issues because it doesn’t provide infrastructure visibility; AlertSpy monitors services through infrastructure signals instead of relying only on basic URL checks.
3. SSL And Domain Expiry Alerts
An expired certificate can take your site offline overnight or can cause accessibility problems. Trust issues among customers are natural and evident, so overlooking domain expiry isn’t an option. But humans are prone to mistakes, so AlertSpy includes
domain and SSL monitoring features that alert teams a week ahead and continuously track these time-sensitive risks before they become avoidable incidents.
4. API And HTTP Endpoint Monitoring
Modern websites depend heavily on APIs and backend endpoints. If an API call fails silently, your app might look fine, but some major problems can grow under the grass. No worries, AlertSpy has the solution for this too. It comes with built-in HTTP monitoring
services that check for failures in custom requests, APIs, authentication flows, and key application endpoints, long before they turn into real damage.
5. Real-Time Notifications
Issues are overwhelming your site for an hour, and you’re only reported about it almost an hour later. Is this even required? Alerts must go out before or at the time it is generated. AlertSpy is built on best monitoring practices that deliver alerts whenever something abnormal happens, through Slack, emails, Microsoft Teams, SMS, or whatever channel you and your team actually use.
6. Incident Tracking And Monitoring History
Every outage tells a story and can come back repeatedly if you reduce your monitoring efforts. AlertSpy keeps a record of every incident. What happened, how long it lasted, what’s responsible, and whether the same problem is recurring. So that teams
can spot patterns and fix the problem once and for all.
7. Dashboard And Reporting
Picture engineers digging through logs just to understand a single incident; then what about diagnosis? That could take months! That’s why our team built a clean dashboard with intuitive features and proper signals for response-time information and status.
At a glance, you can see what’s healthy and what needs attention. Building a report doesn’t even feel like a hectic job.
8. Anomaly Detection
Often, everything looks shipshape, but your smarter monitoring platform still tells you, expertly, that something isn’t on the right track. This is what it does too: whether it’s traffic spikes or odd response times, it will give you a heads-up before
anything big can ruin it.
9. Predictive Monitoring
Everyone wants this catchy feature. It tells you what’s coming your way. Based on historical response times and repeated resource pressure, it can analyze what is at the potential risk. AlertSpy can complement existing server monitoring tools by helping
teams investigate patterns before they become serious service disruptions.
Potential Architecture And Technology Stack Of AlertSpy
TTC approached AlertSpy as a layered monitoring system rather than a single application. At the monitoring layer, distributed checker nodes can perform different checks across websites, APIs, ports, services, and infrastructure. The collected information
then moves through the data capture and processing layers before reaching storage, alerting, dashboards, and notification channels. We use some of the best technologies to provide the best features of Docker, Prometheus, Loki Logs, Kubernetes, Node.js/Go
frameworks, and webhook API integrations. The exact technology used for a particular monitoring component can depend on its workload and operational requirements.
Checker Node Layer
This layer checks your system from top to bottom. Its nodes run across different locations and detect flaws within a second.
Data Capture Stack
As we said, AlertSpy tracks previous records. What causes the failure, what’s responsible, how to avoid it, and even the conversations related to those issues. This is where incident history and performance analysis are covered.
Alerting And Notification Gateway
The alerting layer determines what qualifies as an incident and where to send the notification. AlertSpy’s current notification options include Slack, Microsoft Teams, Google Chat, Discord, and email, and it also supports webhooks for custom integrations.
Dashboard And Analytics
The dashboard gives teams a central view of monitored services. AlertSpy provides response-time analytics so teams can look beyond simple uptime and identify slowdowns that may eventually lead to service problems.
Status And Incident Communication
Alert communication should also extend beyond internal teams. AlertSpy provides white-labeled status pages that organizations can use to communicate maintenance and performance incidents to customers.
Who Can Benefit From The Solution?
AlertSpy is particularly relevant for businesses that depend on websites, APIs, cloud infrastructure, or always-on digital services.
- IT Operations Teams: They can centralize service health and reduce the need to check multiple systems manually.
- DevOps Teams: They can connect monitoring with incident response and existing collaboration workflows.
- System Administrators: They can track infrastructure signals and receive alerts when monitored services behave unexpectedly.
- SaaS Companies: They can monitor customer-facing applications and critical backend services as their infrastructure grows.
- Development Teams: They can use response-time and incident information to investigate application performance issues.
- Growing Businesses: They can start with essential monitoring and expand coverage as their infrastructure becomes more complex.
This matters because Website building costs are only one part of running a digital product. Once a website or application goes live, businesses
also need to think about availability, performance, security, infrastructure, and incident response.
How It Differs From Basic Uptime Monitoring Tools
A basic uptime tool generally answers one question: Is this URL responding? That is useful, but it does not always explain what is happening around the URL. Sometimes it’s important to clear up your confusion between Server Monitoring vs. Server Management.
| Area | Basic Uptime Tool | AlertSpy |
|---|---|---|
| Website Availability | Basic URL check | Website and service monitoring |
| Response Time | Often limited | Continuous response-time analytics |
| SSL | May require separate monitoring | Built-in SSL monitoring |
| Domain Expiry | Often separate | Centralized domain monitoring |
| Anomaly Detection | No, absolutely absent | Yes, present |
| APIs | Basic or unavailable | Advanced HTTP monitoring |
| Infrastructure | Limited | Docker, Prometheus and Loki monitoring |
| Notifications | Usually basic | Multiple communication channels |
| Status Communication | Often unavailable | White-labeled status pages |
| Reporting | Minimal | Visual dashboards + history |
| Incident Visibility | Simple outage record | Centralized incident-oriented monitoring |
| Predictive Insights | High-subscription fees required to access this | Available with reasonable pricing |
| Scalability | Suitable for basic needs | Designed for broader infrastructure visibility |
| Notifications | Mostly through emails, nothing else | Multi-channel, real-time |
AlertSpy System Architecture & Build Flowchart
Here is the step-by-step process flowchart showing how The Tech Clouds (TTC) builds and operates AlertSpy, structured in an unboxed, open-canvas layout that matches your requested workflow
architecture.
│ │
│ TECH STACK ENGINE │
│ │
│ Docker • Kubernetes • Node.js / Go • Prometheus │
│ Loki Logs • Webhook APIs • Analytics Dashboard │
└────────────────────────────────────────────────────────┘
│
▼
┌────────────────────────────────────────────────────────┐
│ │
│ LIVE MONITORING STREAM │
│ │
│ (Real-time Health, Ingestion & Routing) │
└────────────────────────────────────────────────────────┘
│
├──► Distributed Checker Node Layer
│ ├── URL / Uptime Checks
│ ├── SSL Certificate & Domain Expiry
Tracking │
│ ├── API / Advanced HTTP Endpoints
│ └── Container Signals (Docker /
Prometheus) │
│
▼
Data Capture & Normalization Layer
│
├── Continuous Response Time Analytics
└── Loki Log & Metric Ingestion
│
▼
Incident Routing Engine
│
├── Dynamic Threshold & Anomaly Check
└── Alert Dispatcher
│
├──► Real-Time Notifications
Webhooks) │ └── (Slack, Teams, Discord, Email,
│
└──► Customer Status Communication
Status Pages) (White-Labeled Public / Internal
│
▼
┌────────────────────────────────────────────────────────┐
│ │
│ BATCH & ANALYTICS STREAM │
│ │
│ (Long-Term Storage, Pattern & Predictive Models) │
└────────────────────────────────────────────────────────┘
│
├──► Time-Series Data Repository
Records │ └── Historical Performance & Outage
│
▼
Predictive Analytics & Anomaly Engine
│
├── Baseline Performance Evaluation
├── Resource Pressure Forecasting
└── Early Warning Alert Generation
│
▼
Centralized DevOps Dashboard
│
MTTR Reduction └── Comprehensive Reporting, Health Trends &
How the Workflow Processes Data (Layer Breakdown)
1. Ingest & Monitor (Checker Node Layer)
Distributed nodes perform multi-layered monitoring across standard website URLs, custom HTTP/API endpoints, SSL certificates, domains, and container environments (Prometheus/Docker metrics).
2. Stream Data (Live Monitoring Engine)
Monitoring payloads flow in real time through the Data Capture Stack (built with Go/Node.js frameworks) to record response-time metrics and centralize health signals.
3. Evaluate & Route (Proactive Alerting Logic)
The notification gateway processes outages or threshold breaches instantly, triggering real-time alerts across integrated channels (Slack, Teams, Discord, Email) while updating White-Labeled Incident Communication status pages.
4. Store & Analyze (Batch Stream & Predictive Layer)
Historical metric data shifts into batch time-series storage. The system evaluates baseline patterns to fuel anomaly detection and predictive monitoring, helping DevOps teams address resource bottlenecks before service disruption occurs.
Why TTC Built AlertSpy This Way
TTC’s experience building and supporting software systems exposed a recurring issue: infrastructure monitoring becomes harder as applications, APIs, servers, containers, and cloud services multiply. For example, a failed API request can generate
an incident; the alerting engine can route it to the appropriate communication channel; the dashboard can show the affected service, and the incident history can help the team understand whether the problem has happened before. Adding more and more
alerts isn’t the solution. It can make the system too crackly and noisy. So our main goal is to build something with centralized visibility, practical alert routing, response-time analytics, and an architecture that can grow with monitoring needs.
Currently, five monitors and every five-minute check are available in its free plan, with multiple monitoring capabilities, allowing users to start without committing to a large infrastructure investment. Then think: if you subscribe for more, where
would you end up?
Closing Thoughts
In the long run, monitoring isn’t something your teams are afraid to use or see as other paranoia. It should help teams understand what’s happening, why it matters, who’sresponsible, and what can support them in the end. The Tech Clouds (TTC) built
it from real operational challenges, with a focus on practical scalability. If monitoring is becoming harder to manage, TTC can help you explore a simpler approach at your own pace. Beyond monitoring, we can help with project management software tools or custom CRM solutions; call us to discuss your needs.
Frequently Asked Questions
Who can use AlertSpy?
IT Operations teams, DevOps engineers, system administrators, SaaS businesses, and development teams can use AlertSpy to monitor critical services.
Can AlertSpy monitor SSL certificates and domains?
Yes, AlertSpy currently provides notifications a week before your SSL and domain monitoring expires. It also provides alerts for website, ping, port, Prometheus, Docker, and Loki monitoring.
Which notification channels does AlertSpy support?
AlertSpy supports multi-channel notifications. You will get notifications through Slack, Discord, Microsoft Teams, Google Chat, and email, with custom webhooks listed as coming soon.
Can businesses start using AlertSpy for free?
Yes. AlertSpy currently offers a free plan with five monitors and five-minute checks, with paid plans available as monitoring requirements increase.
How is AlertSpy different from other monitoring tools?
AlertSpy goes beyond normal up/down status. It covers server health, SSL certifications, anomaly detection, and issue prediction.
Recent Posts
Related Blogs
Why Does My Server Keep Crashing? Common Causes and Fixes
Has your server crashed in the middle of a critical deployment, taking your uptime, your revenue, and peace of mind with it? You’re not alone. Every year, businesses lose thousands...
Common Server Problems and How to Fix Them: The Complete Guide
KeyTakeaways Most slowdowns occur when CPU stays above 90%, and disk I/O wait exceeds 10–20ms. Focusing on DNS authentication and strengthening firewall rules can prevent network hiccups, which are a...
How to Speed Up Your WordPress Site: The Ultimate Optimization Guide
You have gone above and beyond to build your WordPress site, but when a visitor arrives, the loading wheel starts spinning. First 3 seconds gone, then five and so on....
App Development Cost by Country in 2027: USA vs UK vs India
You may want a web app or mobile app with almost the same features, but you’re still getting three different quotes from three different agencies in three different countries. App...
What Is the Biggest Threat to SEO in 2027?
For years, the basic search journey was simple: someone typed a question, scanned the results, chose a website, and continued reading there. That habit is changing, mostly because of the...
What Is The Difference Between Cloud Computing and Cloud Migration?
Businesses today aren’t just building in the cloud; they are constantly rethinking where and how their systems run. That’s where the concept of cloud migration comes in: moving your on-premises...
How CRM Software Transforms Small Businesses
Running a small business often means wearing multiple hats. One moment you’re responding to customer inquiries, the next moment you’re following up on unpaid invoices or trying to remember which...
How to Hire Dedicated Developers: A Complete Guide from Scratch
Most businesses don't plan to outsource. It happens when your internal teams can’t cope with the demands of the existing market. Suppose a project that requires something which your present...